> ## Documentation Index
> Fetch the complete documentation index at: https://docs.ragen.ai/llms.txt
> Use this file to discover all available pages before exploring further.
# Ragen Brain: Curated Knowledge Pages from Your Documents
> Brain extracts knowledge pages from your documents, cites every statement back to its source, and puts a page in front of chat only after a person approves and publishes it.
Ragen Brain turns the documents in your knowledge base into **knowledge pages** — short, reviewed statements about a policy, a process, a role, an entity or a product, each one citing the exact passage it came from. Alongside the pages it keeps **findings**: what contradicts what, which source has moved on, which page nobody vouches for any more.
The part that matters most is what Brain does *not* do: nothing it writes reaches chat on its own. A page is a candidate until a person approves it, and it is retrievable only after a person publishes it. Publishing can be undone at any time.
Brain is behind the `brain` feature flag, which is **off by default**. Only owners and admins of an organization where the flag is on can open it. See [Turning Brain on](#turning-brain-on).
## How it works
You choose documents and start an extraction. A background job reads each one and writes **candidate** pages. Every statement on a page carries a verbatim quote, and a statement whose quote cannot be found in the document is dropped.
A person sets an owner, checks who the page is open to, and approves, rejects or merges it. Every decision is written to an append-only history.
An approved page with an owner and an access list can be published to the knowledge base. From then on, chat can retrieve it and cite it next to your documents.
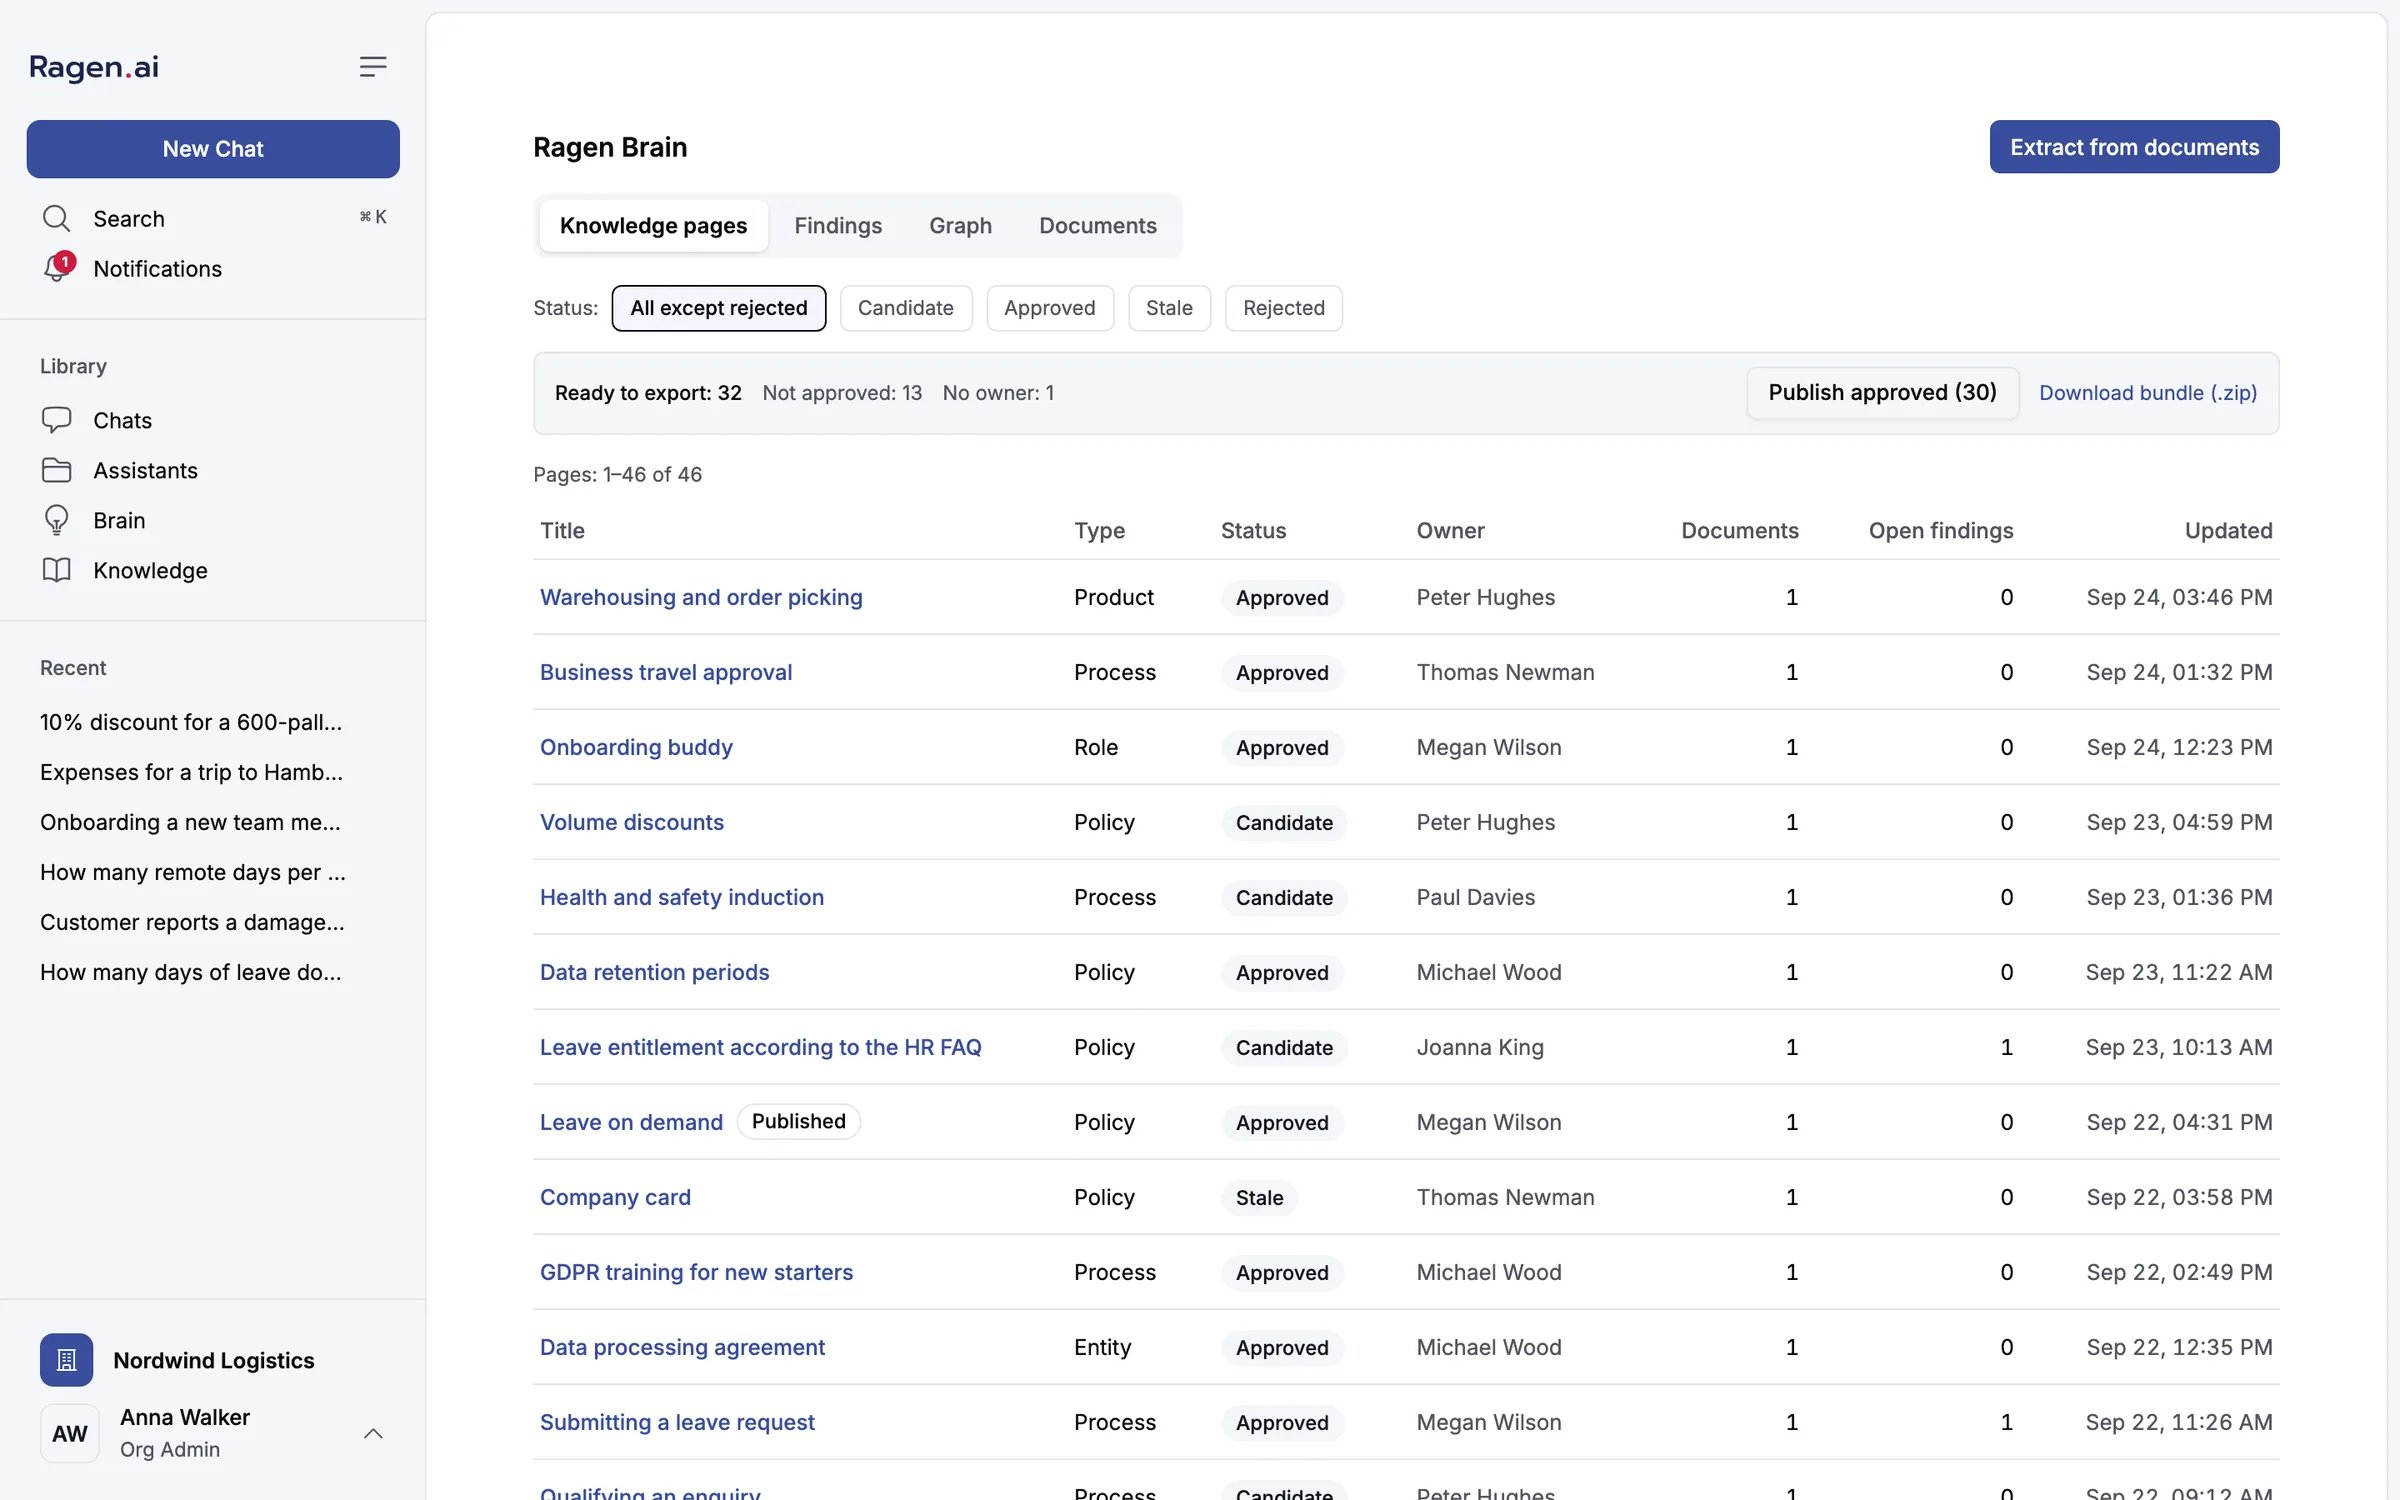
Brain lives in the panel under **Brain**, with four tabs: **Knowledge pages**, **Findings**, **Graph** and **Documents**.
 ## Turning Brain on
The flag is resolved like every other feature flag in Ragen: an organization override wins, then the organization's plan, then the platform default, then the built-in default (`false`). A platform administrator changes it in the [admin panel](/security/admin-panel) under **Features**:
* **For one organization** — pick the organization, set **Ragen Brain** to **Force on**, and save the overrides.
* **For every organization on the installation** — set it under **Platform defaults**. A plan that sets the flag still wins over the platform default.
With the flag on, the **Brain** item appears in the sidebar for that organization's **owners and admins**. Members never see it: every Brain route answers them with a 404, so a disabled feature and a missing one look the same. A platform administrator is not let in by that role alone either — Brain holds the customer's own knowledge.
Turning the flag off hides the panel and stops Brain's background jobs. Nothing is deleted. Pages already published stay in the knowledge base and keep being cited, and a document uploaded into Brain alone can still be sent to the knowledge base from the Knowledge page.
## Extracting knowledge pages
Click **Extract from documents**. The dialog lists the organization's parsed documents and pre-selects the ones no page cites yet. Each row shows how many pages already cite it, or **Not extracted**.
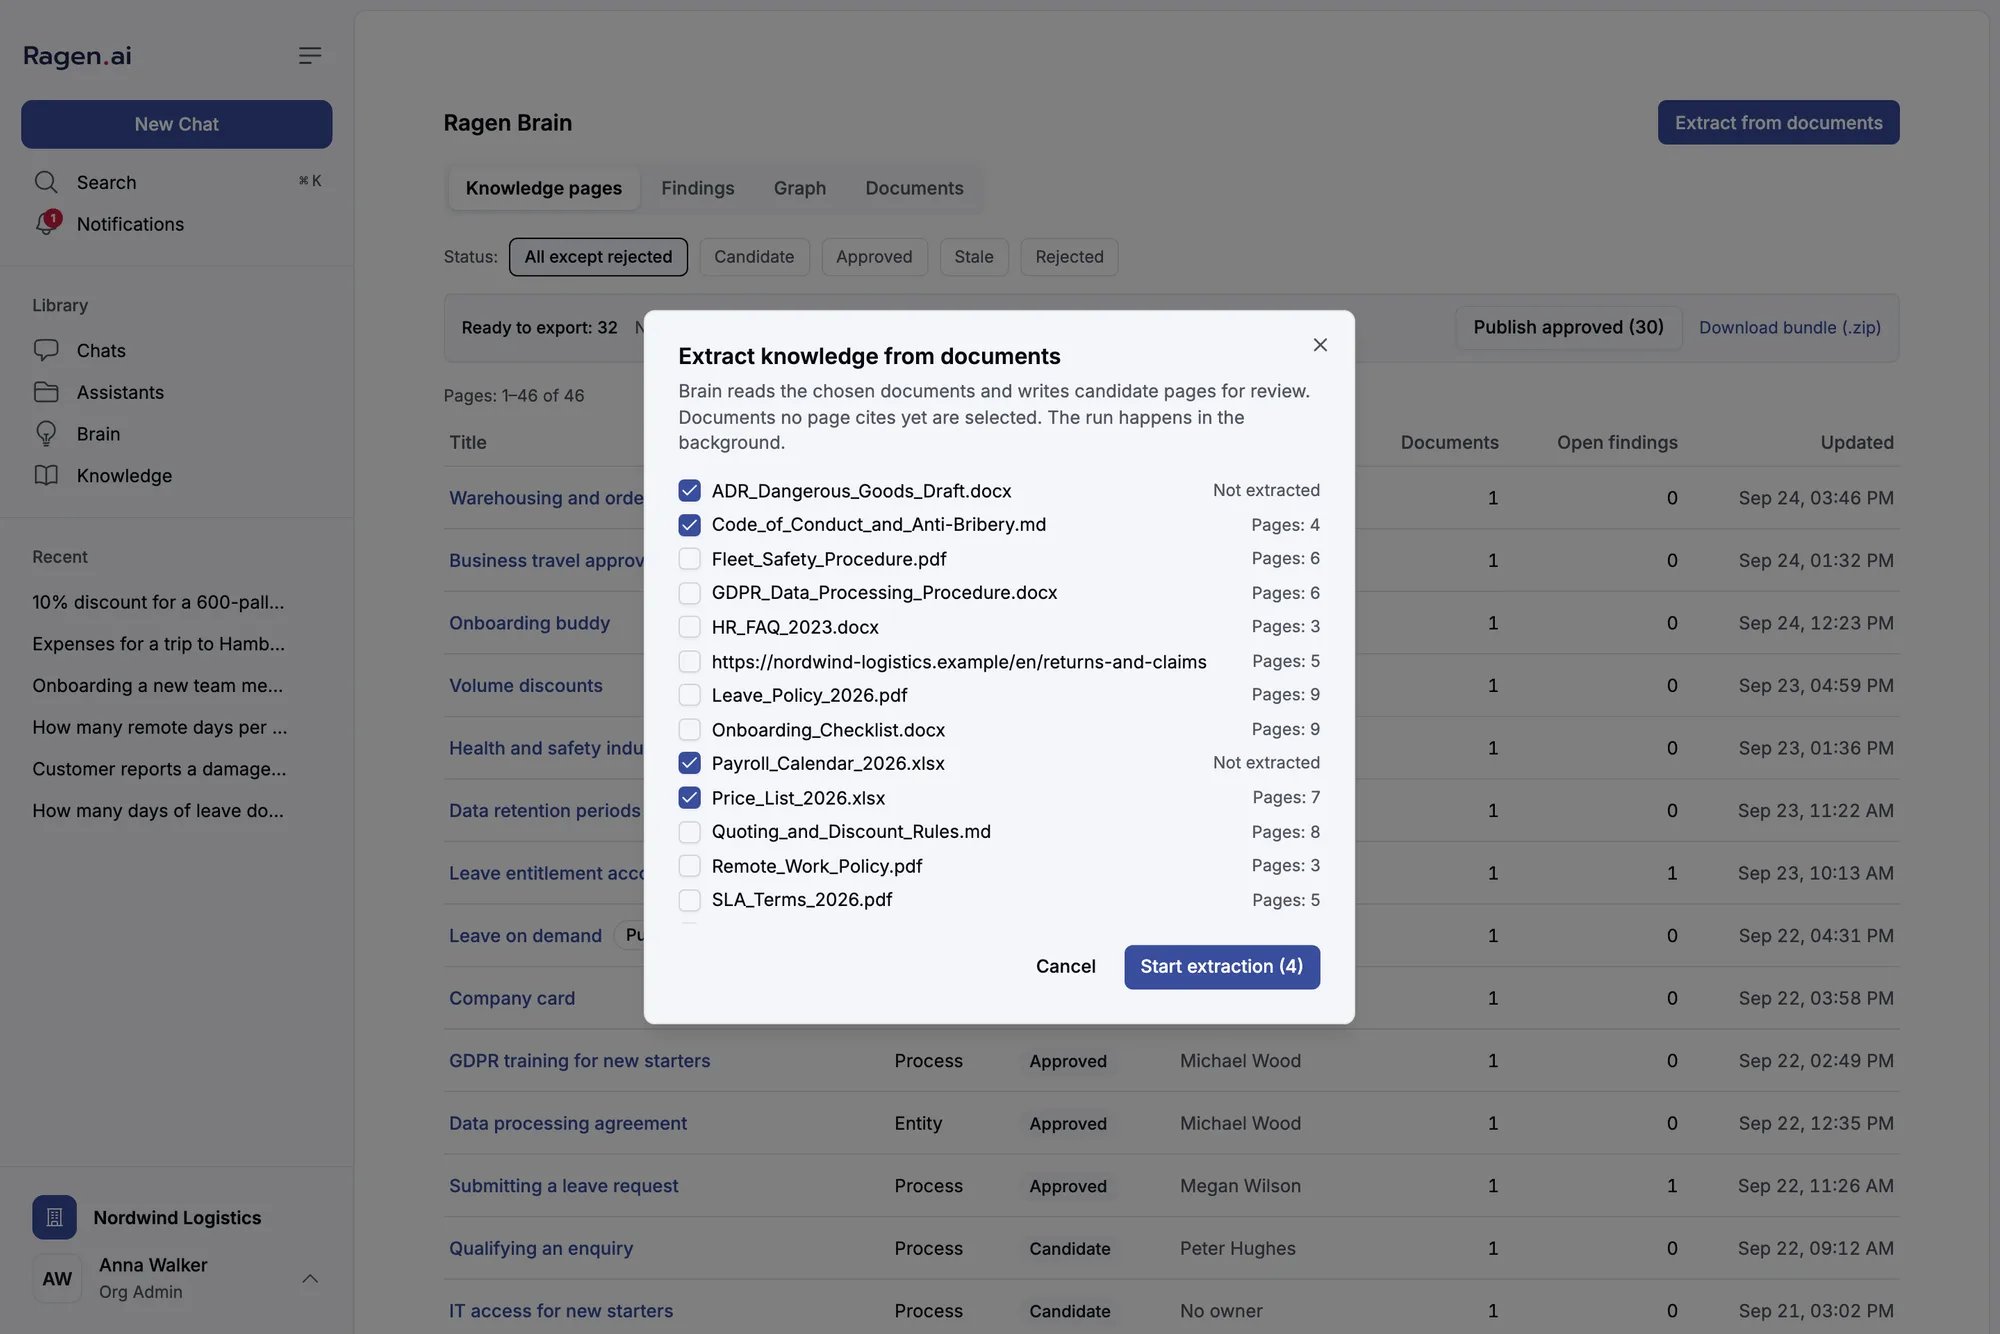 A run takes at most 200 documents and happens in the background; candidates appear as each document finishes. One run executes at a time across the installation by default, so a second run queues behind the first.
What extraction produces:
| Page type | What it describes |
| ----------- | --------------------------------------------------------------------- |
| **Policy** | A rule — leave entitlement, data retention, discounts |
| **Process** | Something people do in steps — submitting a leave request, onboarding |
| **Role** | Who does it — an onboarding buddy, a line manager |
| **Entity** | A thing the organization deals with — a department, an agreement |
| **Product** | What the organization offers — a service line, a price list |
Three rules decide what survives:
* **A statement is kept only if its quote occurs in the document.** The quote is checked against the whole document text, not just the part the model was shown.
* **A subject with no verified statement does not become a page.** It would be a title with nothing behind it.
* **A relation between pages is labelled by its evidence.** One whose quote verifies is shown as *quoted*; one the model says is stated but whose quote does not verify is *unconfirmed*; one offered without a quote is *inferred*.
A new page is open to exactly the people who could read its source document. When a page comes from several documents — after a merge — it is open to the intersection of their readers, never the union.
Extracting the same document again replaces only candidates nobody has touched. A page that already has a decision on it — an owner set, an approval, a rejection — stays, and a rejected page is not offered again.
A document that cannot be extracted raises an **Extraction failed** finding with a **Retry** button. So does a document the run's limits stopped before it was reached.
## Knowledge pages
Each page has a type, a status and, once someone takes responsibility for it, an owner.
| Status | Meaning |
| ------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Candidate** | Written by extraction, waiting for review. Not exported, not publishable. |
| **Approved** | A person confirmed it says what its sources say. Exportable, and publishable once it has an owner and an access list. |
| **Rejected** | A person said no. It stays in Brain as history and is not offered again. |
| **Stale** | An approved page whose check has lapsed. Exported with its status, so the problem is not hidden. Brain does not set this status itself yet — it reports staleness as a finding. |
The list filters by status and shows **All except rejected** by default.
Open a page to see everything a reviewer needs in one place: its statements with numbered citations, the **Sources** with the quoted passage and the document version it was read from, its **Open findings**, and on the side its **Owner**, **Knowledge base** state, who it is **Open to**, **Verification**, **Relations** and **History**.
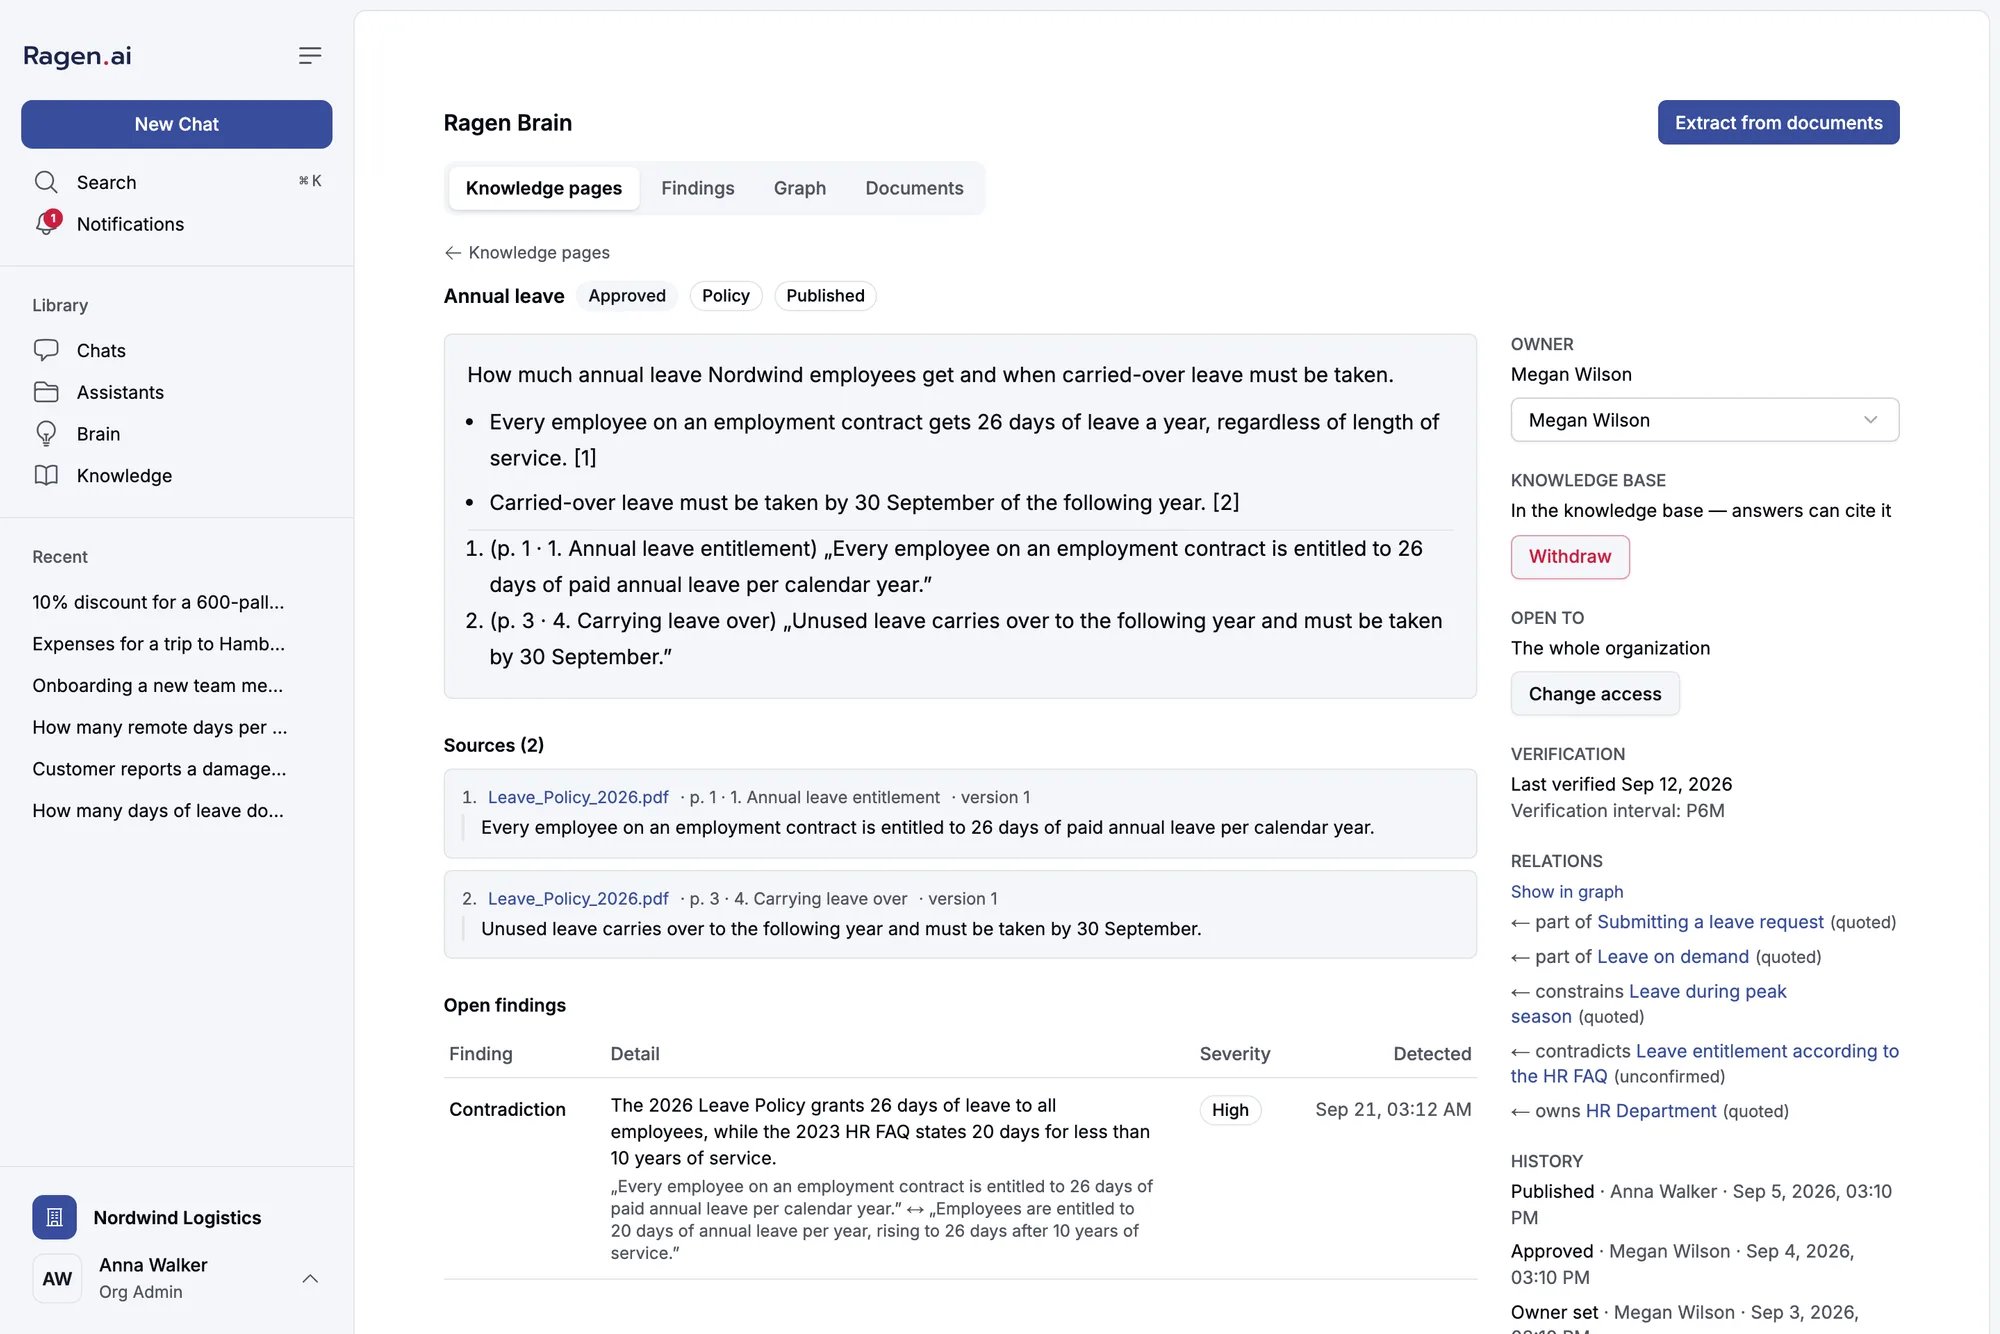 A source is marked when its document has a newer version or has been deleted.
## Reviewing a page
Review is done on the page itself, and only owners and admins can do it.
* **Owner** — the person who vouches for the page, not whoever uploaded the source. Choose a member of the organization and save.
* **Approve page** — available on a candidate that has an owner. The owner must still be a member of the organization.
* **Reject page** — on a candidate. It cannot be undone from the panel.
* **Merge** — fold a candidate into another page about the same subject. Its statements and sources move to the target, which keeps its title, takes the narrower access of the two, and goes back to **Candidate** for review. The merged page is marked rejected and points to the target. The picker suggests pages that look like the same subject first. Neither page may be published.
* **Change access** — choose the whole organization, teams or people. A change that lets anyone read the page who could not before is a **widening**: the panel asks you to confirm it, and it is recorded under your name as **Access widened**. A page open to nobody shows **Nobody yet — needs a decision** and cannot be published.
Every one of these — and every publication and withdrawal — is appended to the page's **History**, with who did it and when. The history cannot be edited.
## Findings
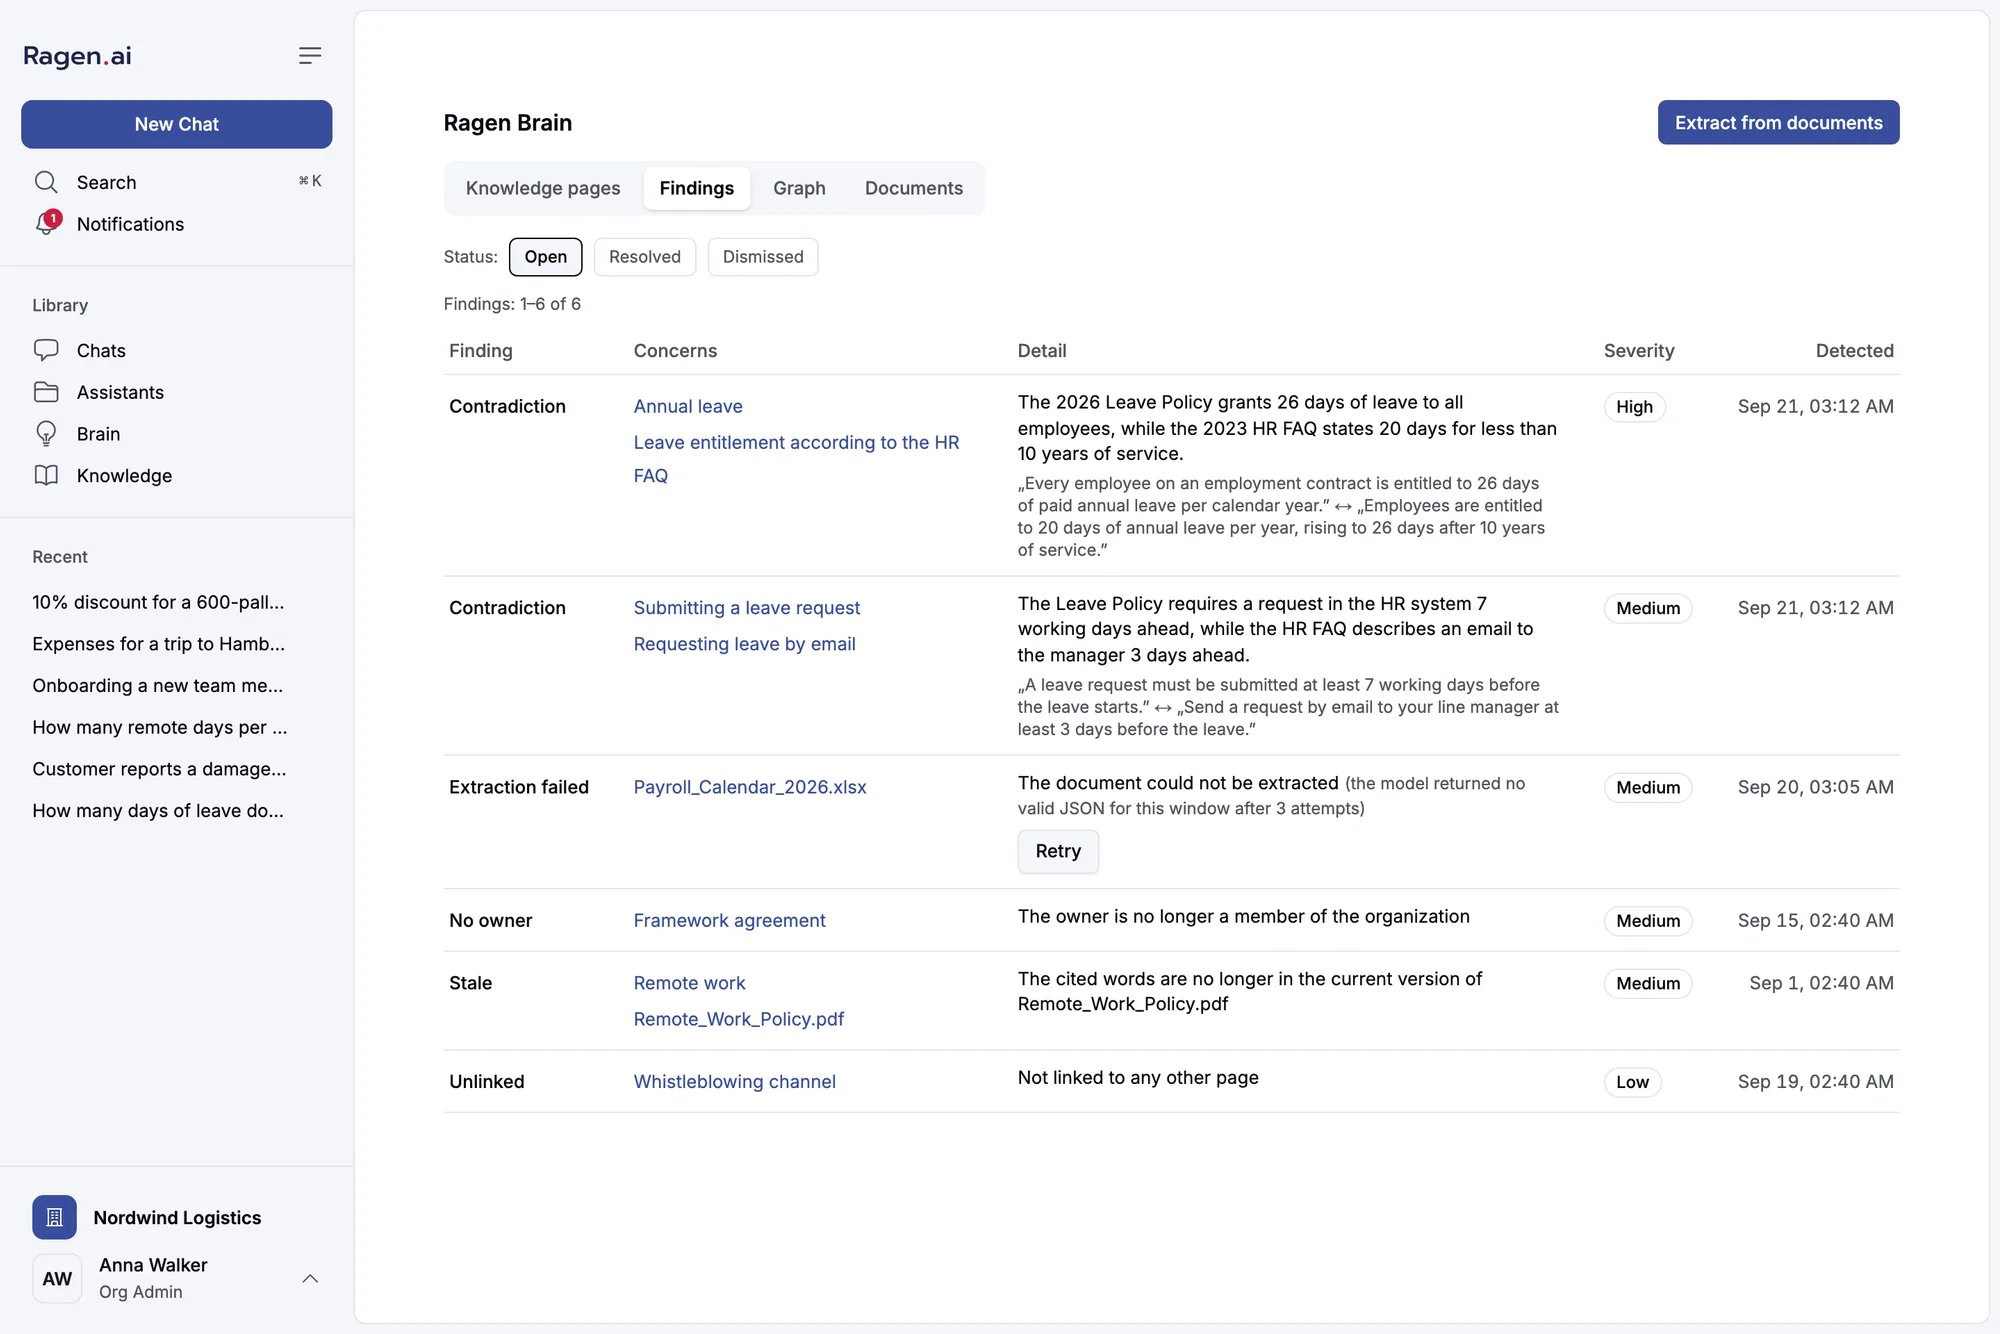
The **Findings** tab is the list of things a curator should look at, filtered by **Open**, **Resolved** or **Dismissed**.
 | Finding | Raised when | Severity |
| --------------------- | ----------------------------------------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------- |
| **Contradiction** | A model judges that two pages on the same subject, built from different documents, disagree. The detail quotes both passages. | **High** if either page is published, otherwise **Medium** |
| **Stale** | A source document was deleted, or its current version no longer contains the quoted words, or a page's verification interval has elapsed. | **High** on a published page for a source problem, otherwise **Medium** |
| **No owner** | An approved page has no owner, or its owner is no longer a member of the organization. | **High** if published, otherwise **Medium** |
| **Unlinked** | An approved page has no relation to any other page. | **Low** |
| **Gap** | An approved **Process** page has no relation to any **Role** page — nobody is named as performing it. | **Low** |
| **Extraction failed** | A document could not be extracted, or the run's limits stopped before it. | **Medium** |
A new version of a document is not enough to make a page stale. Re-uploading the same PDF creates a new version with the same text, so Brain checks whether the quoted words are still there.
**Stale**, **No owner**, **Unlinked** and **Gap** are computed from the pages themselves. Brain recomputes them at the end of every extraction run and after every review or publication decision, and resolves a finding on its own once its cause is gone — set an owner and the **No owner** finding closes. Candidates are left out on purpose: every candidate is unowned and unlinked until someone reviews it.
**Contradiction** is judged only when an extraction run writes one of the two pages. **Extraction failed** closes when the document extracts successfully, for example after **Retry**.
## Graph
The **Graph** tab draws the pages and the relations between them. Click a page to see its relations and open findings, then **Open page** or **Show neighbourhood** to focus on it.
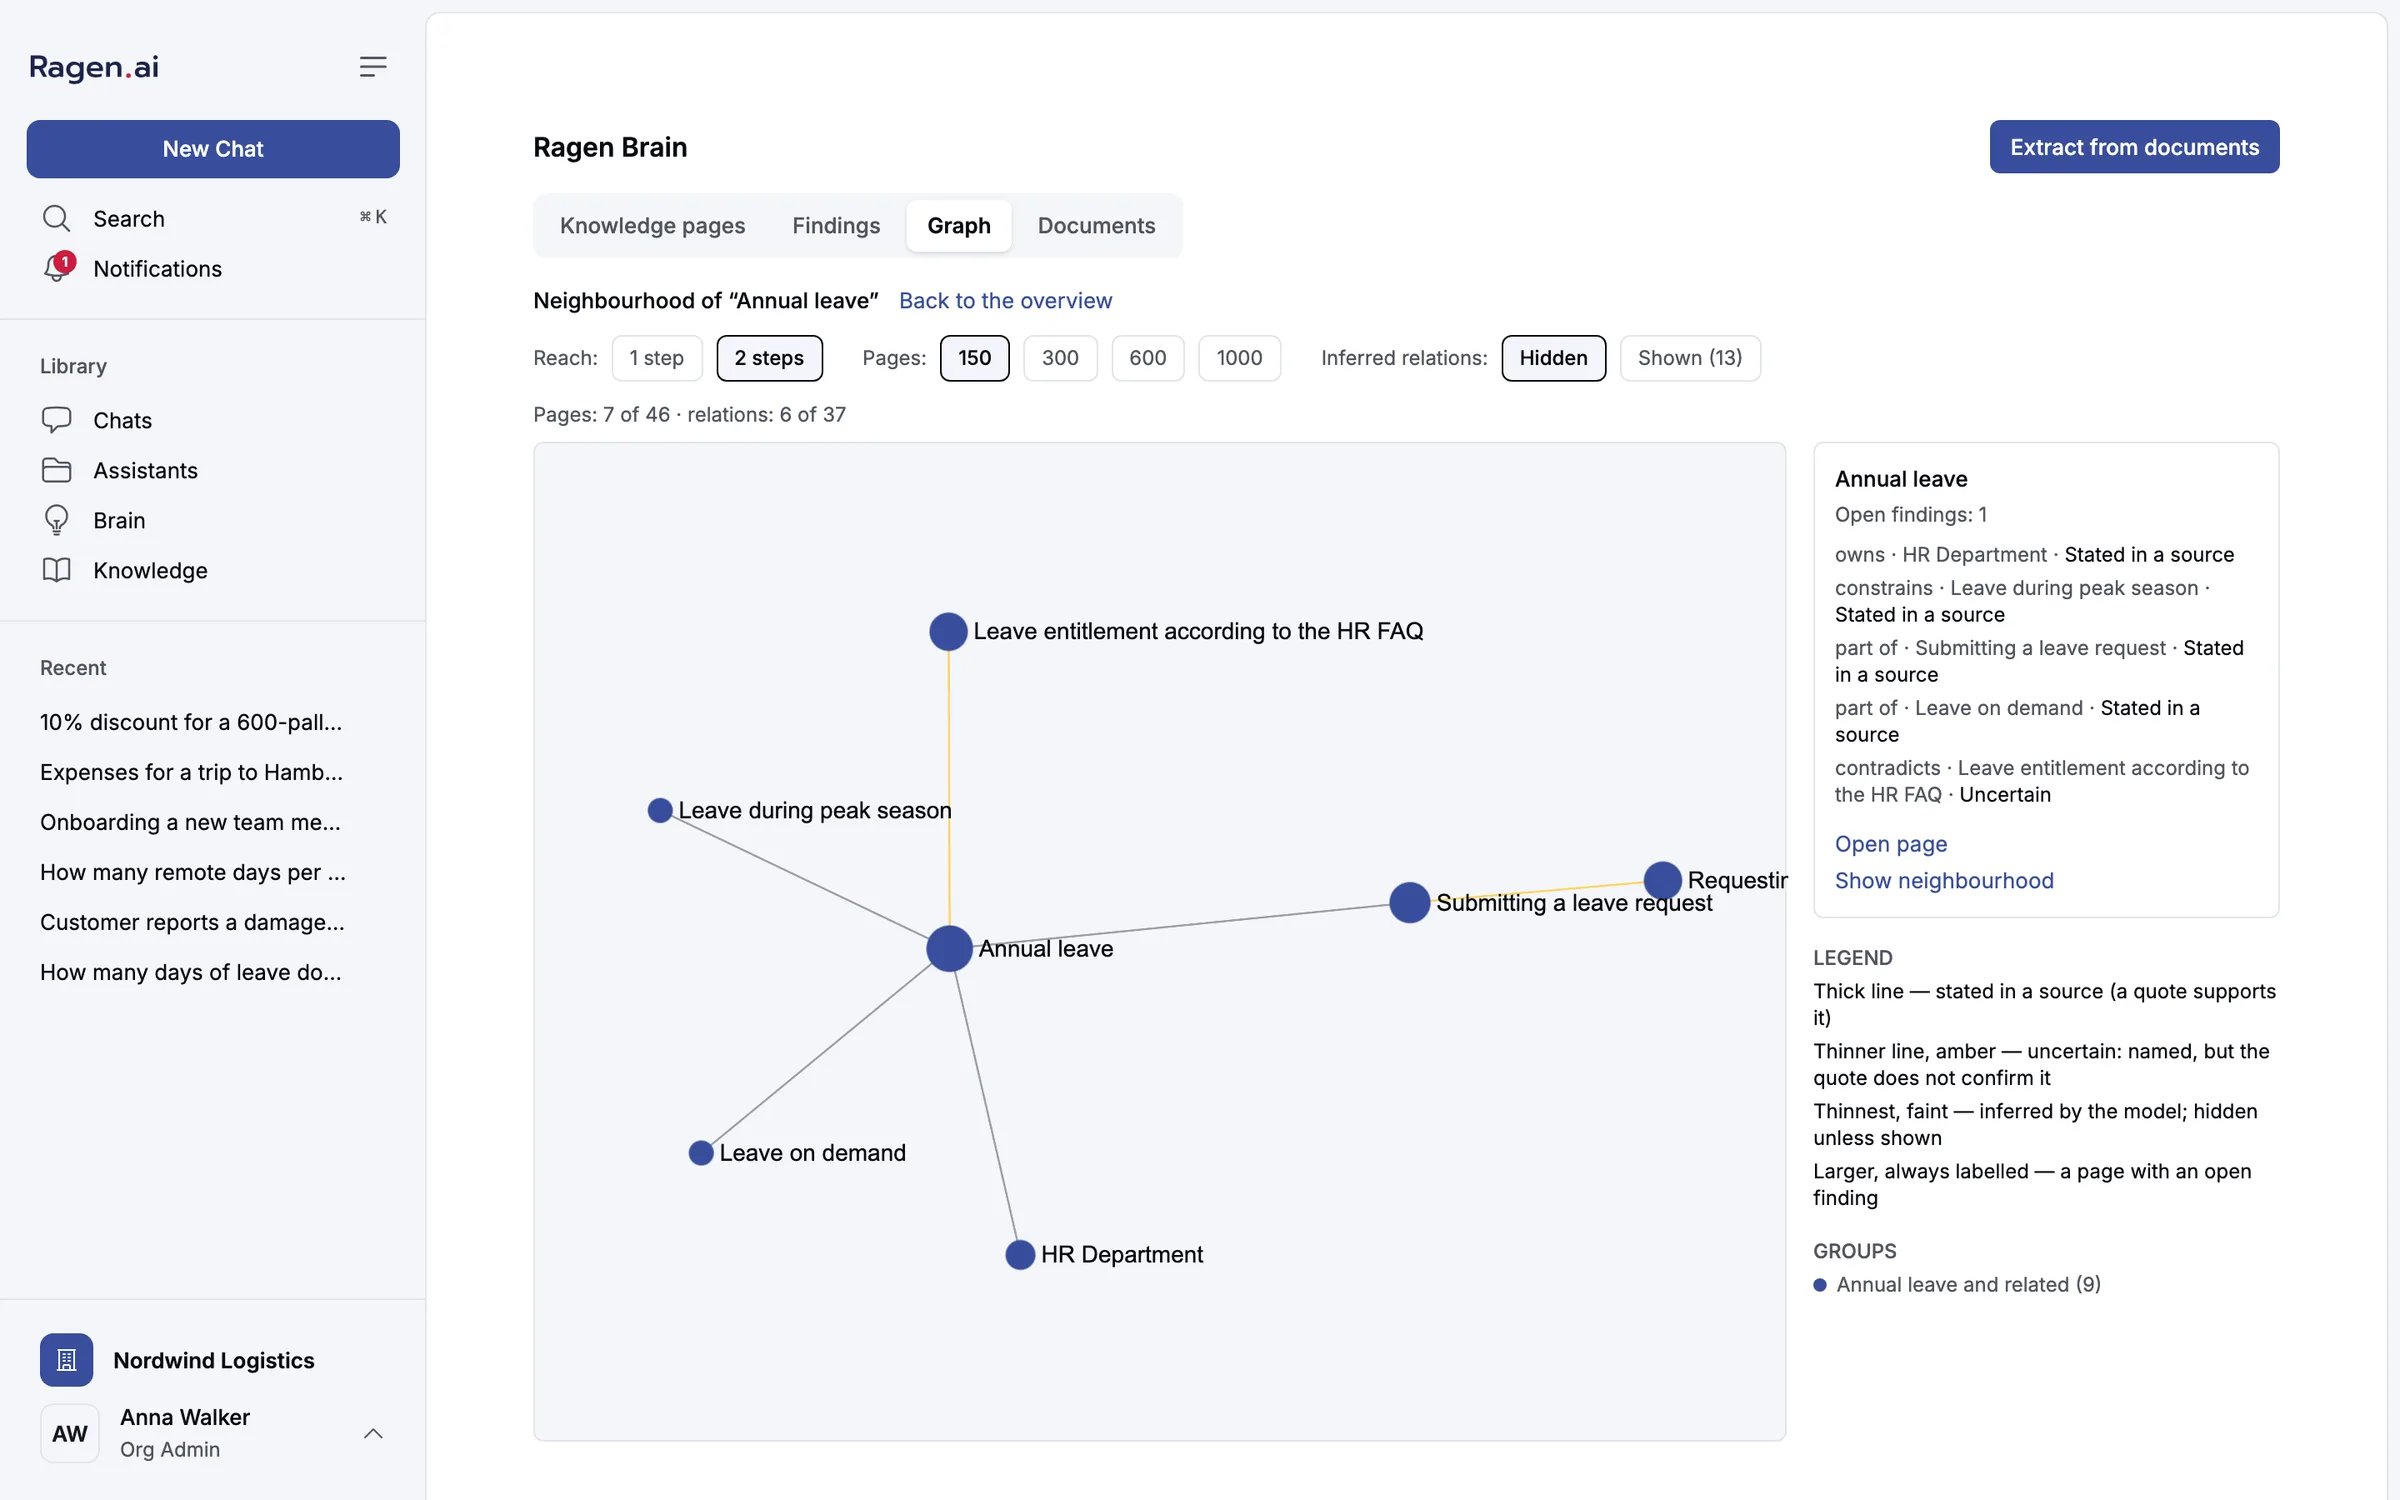 * **Reach** — how far out a neighbourhood goes: **1 step** or **2 steps**.
* **Pages** — how many pages to draw at most: 150, 300, 600 or 1000. The line under the controls says how many of the total are shown.
* **Inferred relations** — **Hidden** by default. Relations the model inferred without a quote are the weakest evidence, so they are never shown unless you ask.
Line weight follows the evidence: thick for a quoted relation, thinner and amber for an unconfirmed one, thinnest and faint for an inferred one. A page with an open finding is drawn larger and always labelled. **Groups** lists clusters of closely related pages.
## Documents
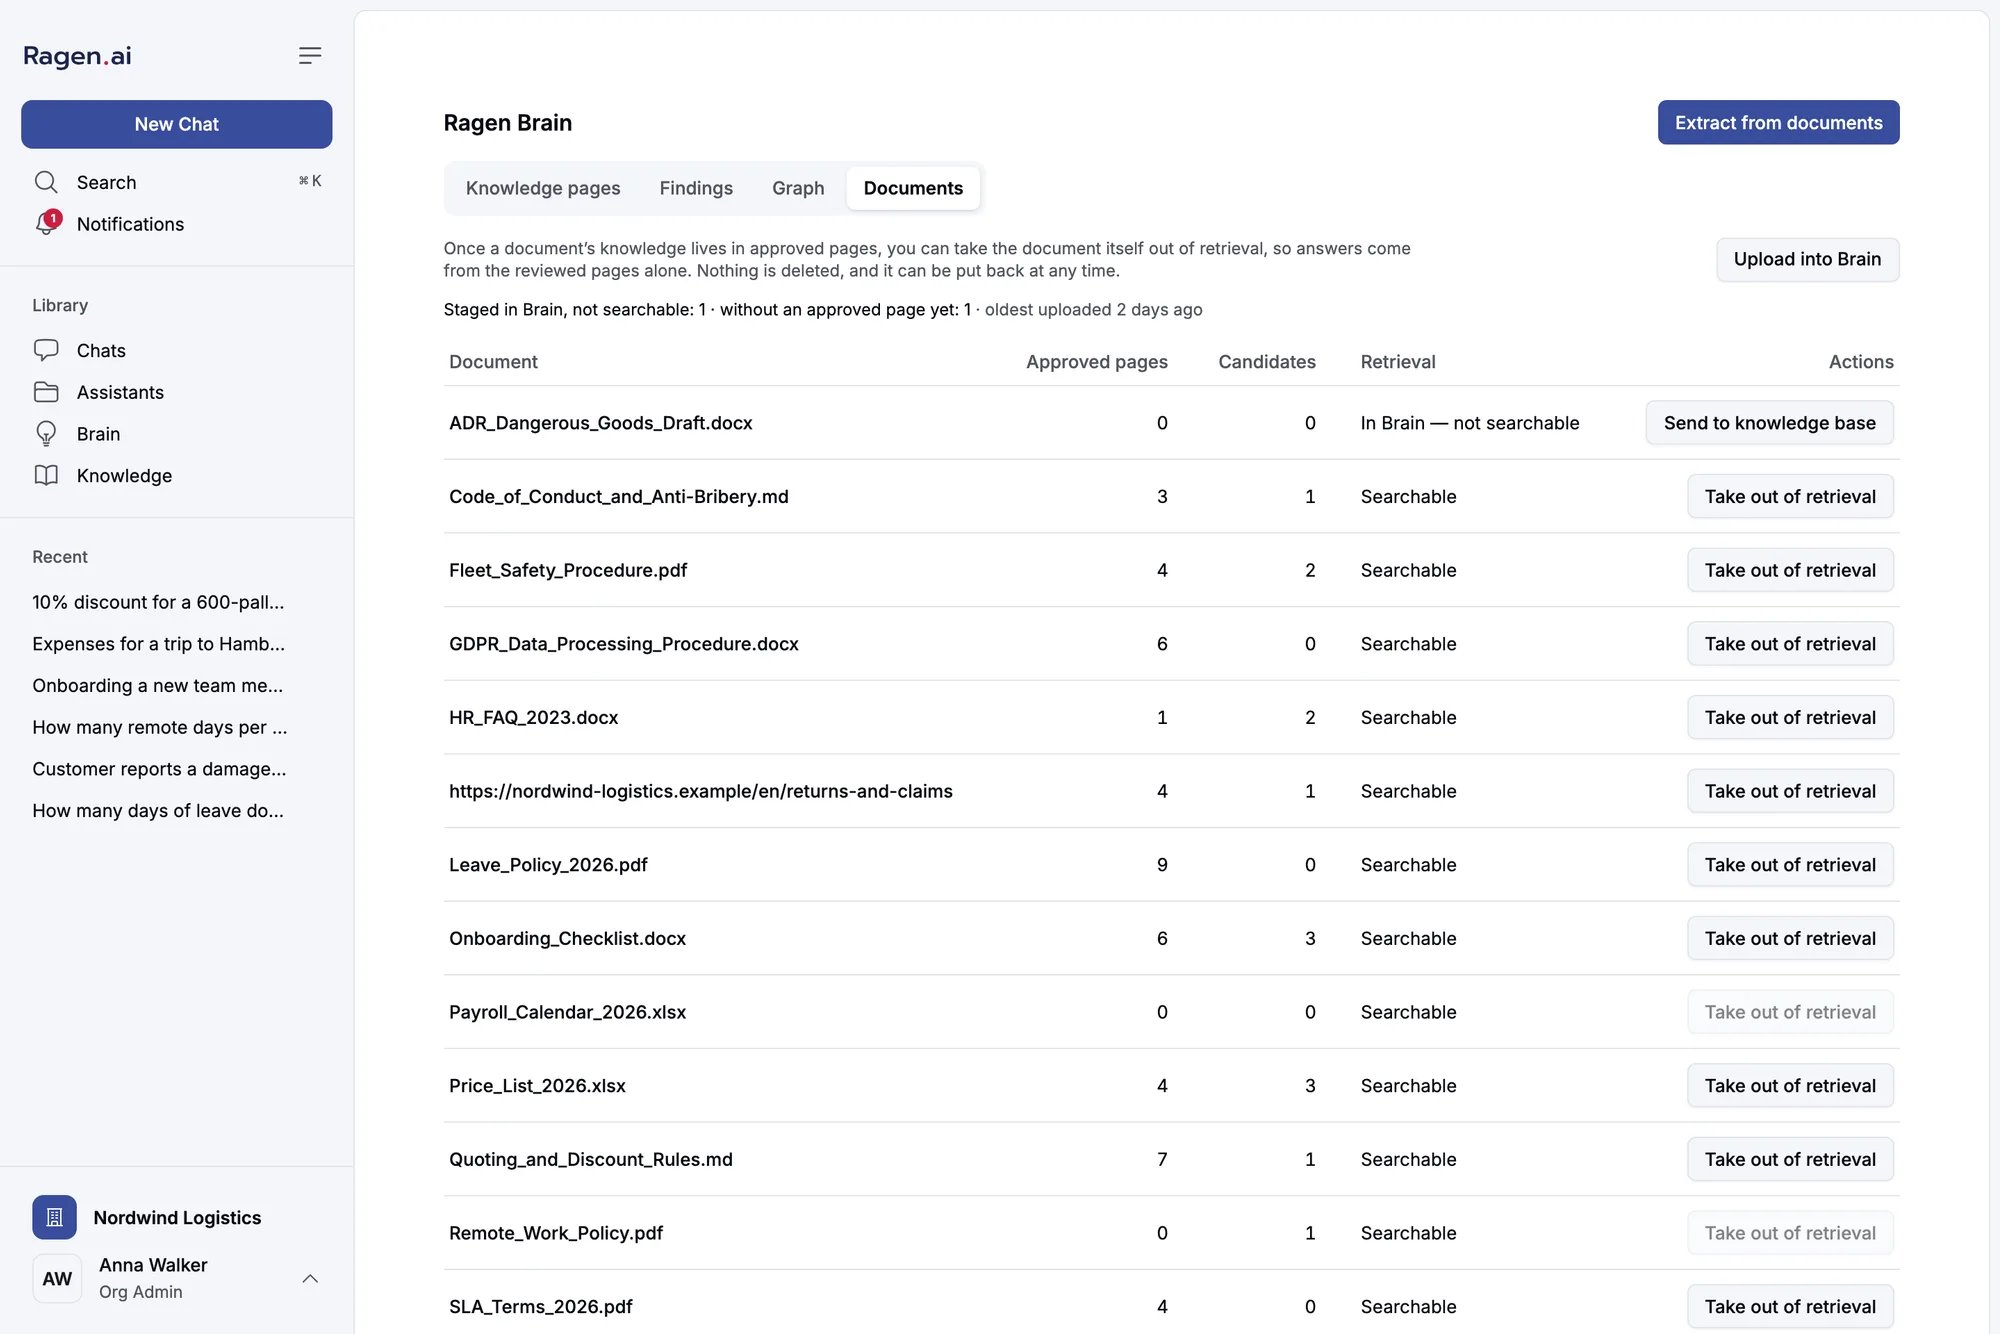
The **Documents** tab shows, for each document, how many approved pages and candidates cite it and whether it is in retrieval.
 ### Taking a document out of retrieval
Once a document's knowledge lives in approved pages, you can **Take out of retrieval**, so answers draw on the reviewed pages instead of the raw document. The action is available only when at least one approved page cites the document. Nothing is deleted — the document, its versions and every citation stay — and it stays out even when the knowledge base re-processes files later. **Put back** re-indexes it exactly as an upload would.
Brain never does this on its own. It is always a person's decision, per document.
### Uploading into Brain alone
**Upload into Brain** stores and parses files without indexing them. They show as **In Brain — not searchable**: you can extract pages from them, and while a document stays staged nothing in it can be retrieved or cited — only a published page built from it can reach an answer. This is the way to curate a sensitive corpus before any of it can reach an answer. The protection lasts only as long as the document stays out of retrieval: sending it to the knowledge base (below) makes the whole document searchable.
To index a staged document as an ordinary one, use **Send to knowledge base**. The same action is offered on the Knowledge page and does not depend on the `brain` flag, so staged files are never stranded if Brain is switched off.
## Publishing to the knowledge base
On an approved page, **Publish to knowledge base** writes it into the index as its own document, with the page's access list on every chunk. The panel explains what is missing if the button is not available: the page must be approved, have an owner, and be open to someone.
The page's **Knowledge base** state tells you where it is:
| State | Meaning |
| ------------------------------------------- | ----------------------------------------------------- |
| Not in the knowledge base | Never published |
| Being written to the knowledge base… | Publication is in progress |
| In the knowledge base — answers can cite it | Serving |
| Withdrawn from the knowledge base | Withdrawn; still approved, and can be published again |
| Writing to the knowledge base failed | Publish again to finish |
If a page's text changes after it was published, the panel says so and offers **Republish**.
**Withdraw** takes the page out of the index. Answers stop citing it immediately, the page stays approved, and past answers keep their citations.
**Publish approved** on the Knowledge pages tab publishes every approved page in one go. Pages already serving their current text are left alone, changed pages are republished, and pages without an owner or open to nobody are skipped and counted. Withdrawn pages stay withdrawn.
Changing who a published page is open to reaches the index, not just the page: the page's chunks are removed and written again with the new access. In between, the page answers nobody — stricter than either the old or the new setting.
## Brain pages in chat answers
A published page is retrieved like any document, under its own access list. When an answer cites one, the source card is labelled **Brain page** and lists the documents it is **based on**, with the section of each.
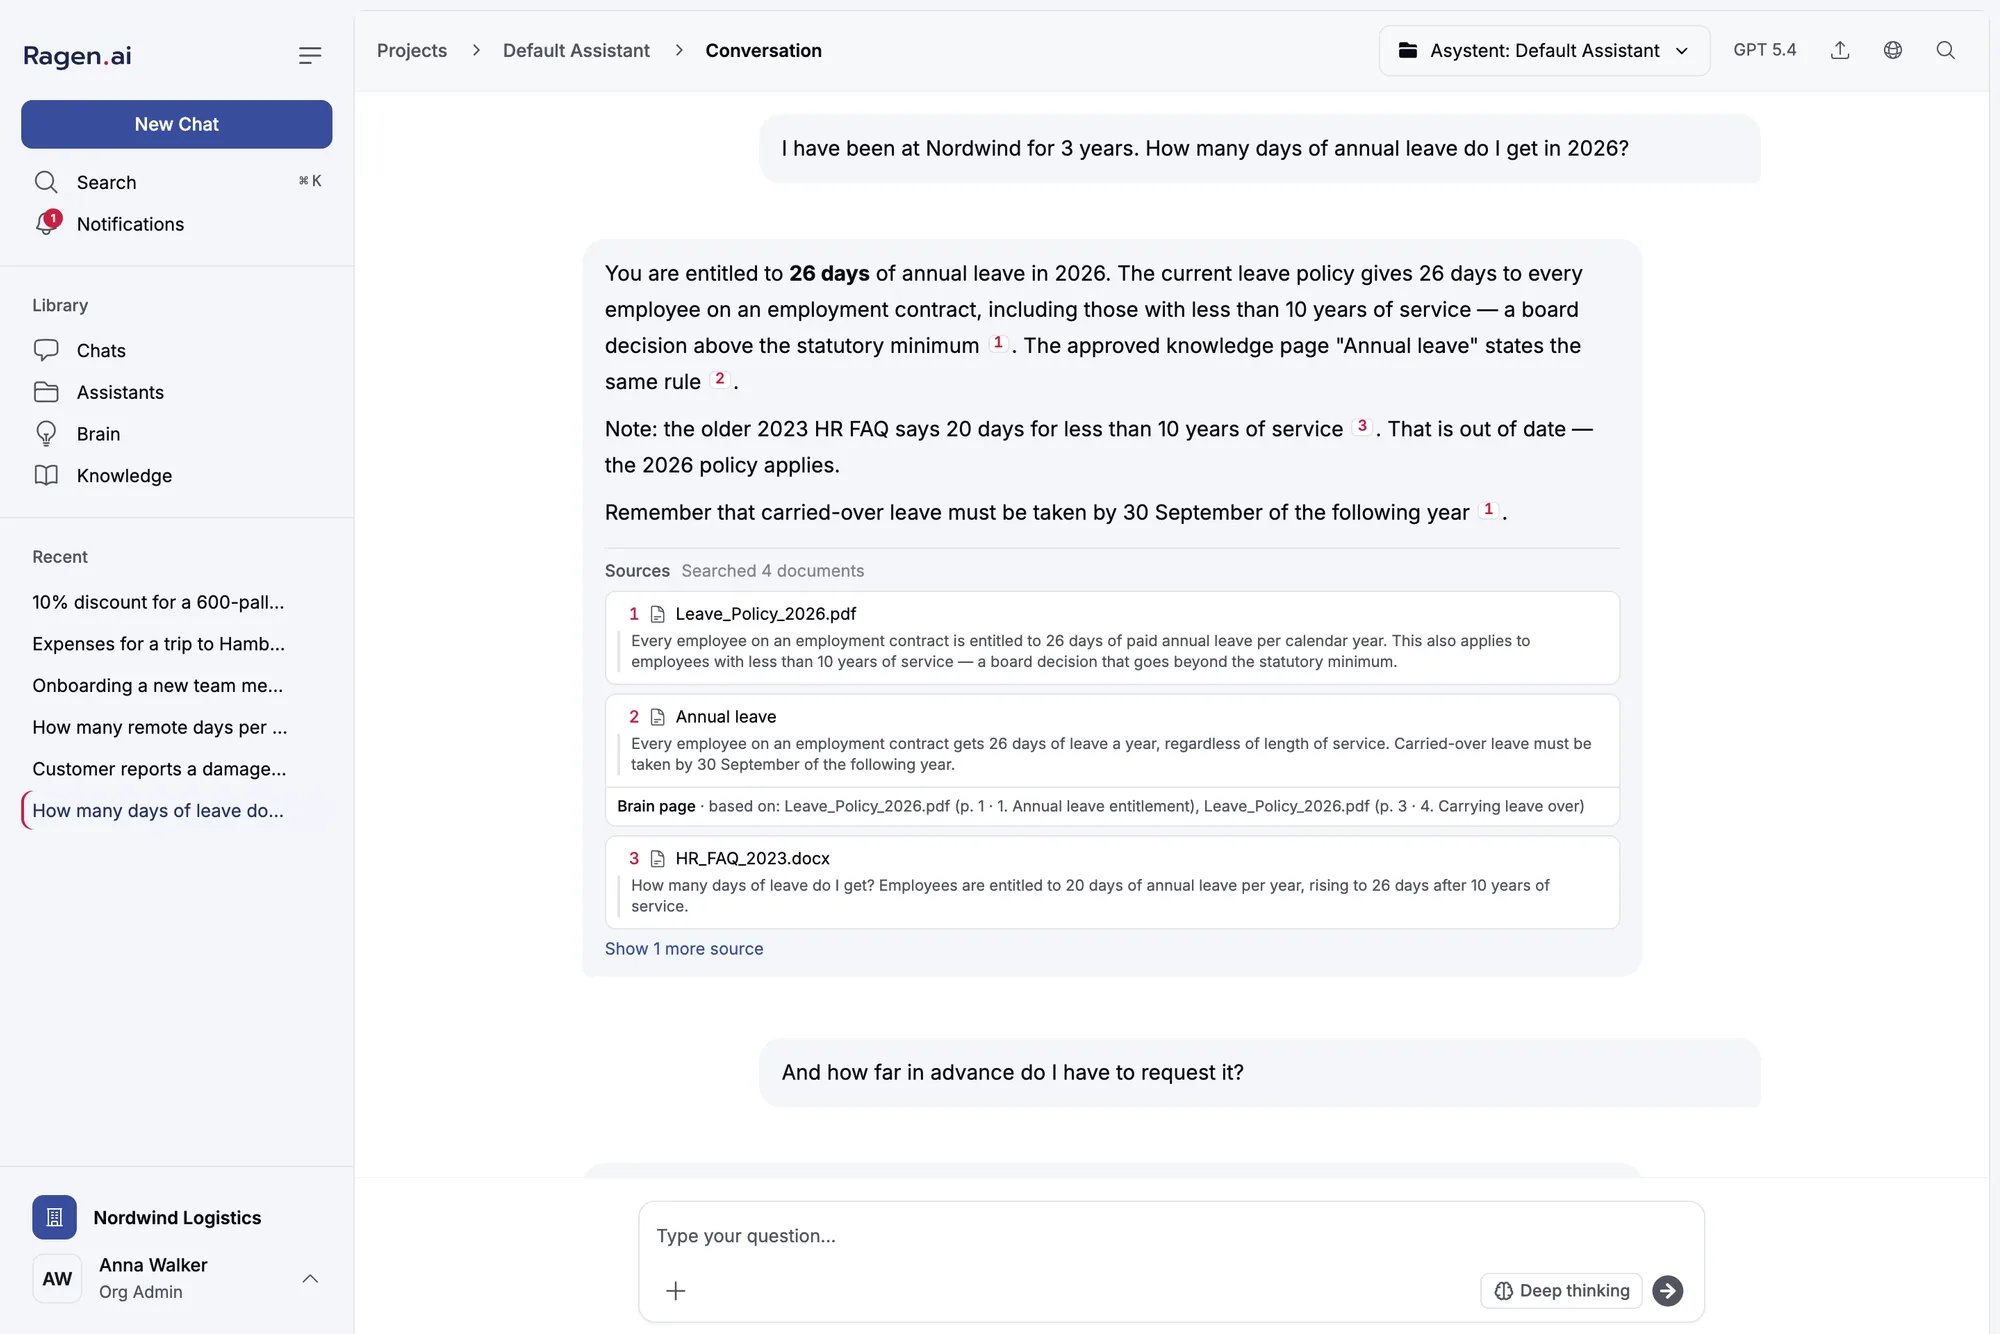 A reader sees only the source documents they are allowed to open. If a page was widened to someone who cannot read any of its sources, they see the page and **none of its sources are visible to you** in place of the list.
## Exporting a bundle
**Download bundle (.zip)** on the Knowledge pages tab exports the organization's curated knowledge as files you can read without Ragen:
```
ragen-brain-2026-09-24.zip
├── manifest.json # every page, with its path and content hash
├── graph.json # the relations between exported pages
└── pages/
├── annual-leave.md # frontmatter: type, status, owner, access, sources
└── ...
```
Only **Approved** and **Stale** pages are exported, and only those with an owner, an access list and at least one source. The bar above the list counts what is ready and why the rest is left out — **Not approved**, **No owner**, **Open to nobody**, **No sources**.
## From the terminal
The Ragen CLI has a read-only `ragen brain` command that reads the same data through the public API with an API key of an owner or admin: `next`, `doctor`, `findings`, `pages`, `graph`, `query` and `export`. Approving, merging and publishing stay in the panel, where the reviewer sees the sources and the access they are deciding about.
`ragen brain` is on `main` but not yet in a published release of `ragen-cli` — `0.1.0` predates it. See [CLI](/cli).
## Configuration
Brain's extraction runs on the worker. These variables are read there; all are optional.
| Variable | Default | What it controls |
| ----------------------------- | --------------- | --------------------------------------------------------- |
| `BRAIN_EXTRACT_MODEL` | `SUMMARY_MODEL` | The model that extracts pages and judges contradictions |
| `BRAIN_EXTRACT_MAX_DOCUMENTS` | `200` | Documents one run may extract |
| `BRAIN_EXTRACT_MAX_TOKENS` | `2000000` | Tokens one run may spend, across all its documents |
| `BRAIN_EXTRACT_CONCURRENCY` | `1` | Extraction runs executing at once across the installation |
A run that hits either ceiling stops, and the documents it did not reach get an **Extraction failed** finding you can retry. Each run compares at most 100 page pairs for contradictions.
Extraction makes several model calls per document. Raise `BRAIN_EXTRACT_CONCURRENCY` only with a provider quota you have measured — two parallel runs were enough to hit rate limits in testing.
## Current limits
* **Contradictions are looked for between pages with the same title.** Two documents that name one subject differently — "Leave" and "Annual leave" — are not compared, and the check runs only when extraction writes one of the two pages, so merging them in review does not trigger it either. Review differently titled pages on the same subject yourself; merging them afterwards keeps one page, but does not check its sources against each other.
* **Verification is read-only.** A page shows its verification interval and last verification when they are set, and the **Stale** finding fires when the interval lapses, but the panel cannot set an interval or record a verification yet.
* **A page's status does not turn to Stale by itself.** Staleness is reported as a **Stale** finding on the approved page.
* **Findings cannot be dismissed from the panel yet.** The computed ones close on their own once their cause is fixed.
* **Only a candidate can be approved or rejected.** Retiring an approved page means withdrawing it from the knowledge base.